Computer Vision — Beginner
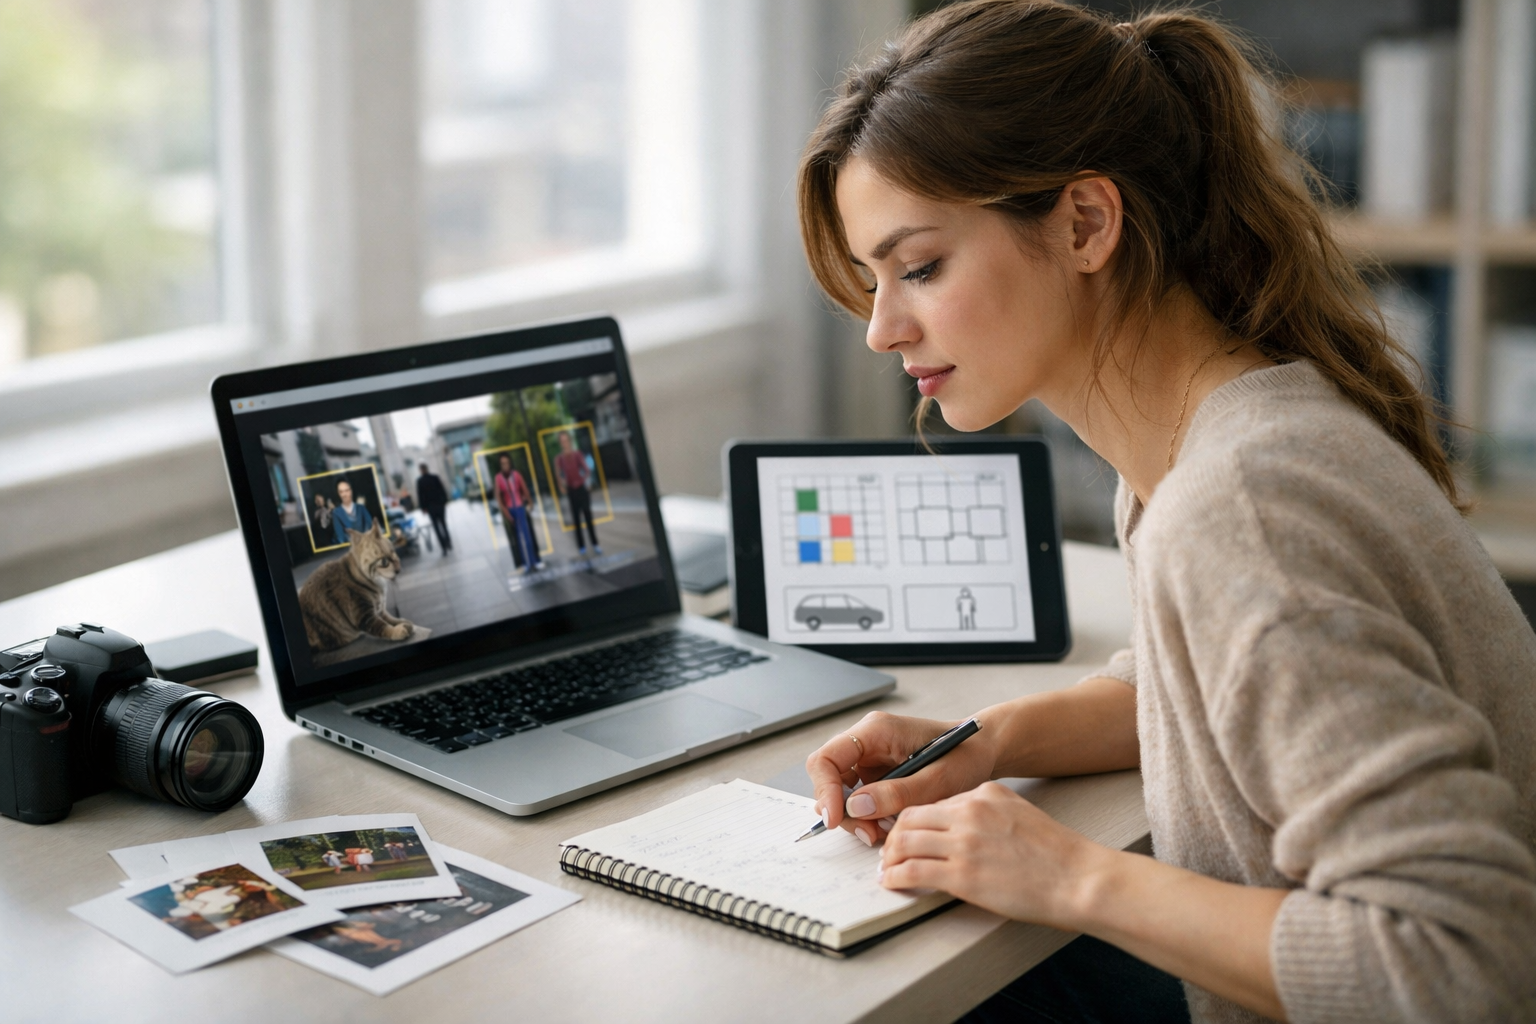
See how AI turns pixels into meaning, step by step.
AI Eyes for Beginners is a short, book-style course designed for complete newcomers who want to understand how computers make sense of photos and video. You do not need any background in artificial intelligence, coding, math, or data science. The course starts with the most basic question: what does it mean for a machine to “see”? From there, it builds a clear and simple explanation of how images become data, how patterns are found, and how real computer vision systems are used in the world.
Many people hear terms like image recognition, object detection, or facial recognition without knowing what they actually mean. This course removes the mystery. You will learn the key ideas in plain language, with a strong focus on intuition instead of technical complexity. By the end, you will be able to explain common computer vision concepts with confidence and understand the strengths and limits of these systems.
This course is organized like a beginner-friendly technical book with six connected chapters. Each chapter builds on the one before it, so you never feel lost. First, you learn what computer vision is and where it appears in everyday life. Next, you discover how images are made of pixels, color, and frames. Then you move into how computers find patterns, how machine learning uses examples, and why labels matter.
Once the foundation is strong, the course introduces the main jobs of computer vision, including classification, detection, segmentation, and tracking. After that, you will learn how vision systems are trained, tested, and improved, including beginner-level ideas about accuracy, bias, and confidence scores. Finally, the course closes with practical real-world uses and a roadmap for what to explore next.
If you have ever wondered how a phone camera recognizes faces, how self-checkout systems identify products, or how traffic cameras count vehicles, this course will give you a practical understanding of the ideas behind those tools. It is not about turning you into an engineer overnight. It is about helping you build strong mental models so you can understand, discuss, and evaluate computer vision with confidence.
This course is ideal for curious beginners, students, career switchers, business professionals, and anyone who wants a simple introduction to computer vision. It is also useful if you work near AI projects and want to understand what image and video systems can actually do. Because the course avoids unnecessary complexity, it is especially helpful for learners who feel intimidated by technical topics.
Whether you want a foundation for future AI learning or just want to understand the technology shaping cameras, apps, stores, and smart devices, this course is a strong starting point. You can Register free to begin, or browse all courses if you want to compare related beginner topics first.
AI Eyes for Beginners gives you a calm, clear entry point into one of the most important areas of modern artificial intelligence. If you are starting from zero and want a practical, human-friendly explanation of how computers see the visual world, this course was made for you.
Computer Vision Instructor
This course is written and kept up to date by the Edu AI Last Faculty, the course team of Edu AI Last. If you have a question about any lesson, ask the course assistant on this page at any time.
Computer vision is the field of artificial intelligence that helps computers work with images and video in a useful way. A person can glance at a photo and instantly notice faces, objects, motion, shadows, and even the mood of a scene. A computer does not experience an image like that. It receives numbers. The work of computer vision is to turn those numbers into decisions, descriptions, and actions. In simple terms, computer vision teaches machines how to extract meaning from visual data.
This chapter gives you a beginner-friendly mental model for how that happens. You will see that an image is not magic to a computer. It is a grid of pixels, where each pixel stores values related to light and color. A video is simply many images shown in sequence, with time added as an extra ingredient. From there, vision systems look for patterns: edges, shapes, textures, colors, movement, and repeated visual structures. Those patterns help a model answer questions such as: What is in this image? Where is it? Which pixels belong to it? Is it moving? Is it safe or unusual?
As you begin learning computer vision, it helps to separate a few tasks that beginners often mix together. Classification assigns one or more labels to an entire image, such as saying a picture contains a cat. Detection goes further and locates objects with boxes, such as drawing a rectangle around each cat in the image. Segmentation is more detailed still, assigning a label to each relevant pixel, such as marking the exact outline of the cat rather than just placing a box around it. These are different levels of visual understanding, and each is useful in different real-world systems.
Another core idea is that modern vision systems usually learn from examples. Developers collect training data, attach labels, and use those labeled examples to train a model. The model learns statistical patterns that connect image features to useful outputs. When the model runs on a new image, it may produce a label, a bounding box, a mask, or a confidence score. That confidence score is not a guarantee. It is a numerical expression of how strongly the model supports a prediction based on what it has learned.
Good engineering judgment matters from the very start. A vision system is not just a model. It depends on camera quality, lighting, angle, motion blur, data coverage, and the way results are interpreted in the final application. Many beginner mistakes come from assuming the model alone determines success. In practice, the whole pipeline matters: how the image is captured, how it is cleaned, how labels are defined, how outputs are reviewed, and what action is taken when the model is uncertain.
By the end of this chapter, you should be able to explain computer vision in plain language, describe how digital images are represented, understand how models find patterns in photos and video, distinguish classification from detection and segmentation, and read common outputs like boxes, labels, and confidence scores. Most importantly, you will start to think like a builder: not just what a system predicts, but how and why it reaches that prediction in the first place.
Practice note for Meet the idea of computer vision: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
Practice note for See where vision AI appears in daily life: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
Practice note for Understand the difference between human sight and machine sight: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
When people say a computer can see, they do not mean it sees the way humans do. Human sight is tied to biology, memory, attention, and context. You can recognize a friend from a blurry photo because your brain fills in gaps using years of experience. A computer does not have that natural understanding. It processes arrays of numbers and applies learned rules or learned statistical patterns to them.
So what does “seeing” mean in engineering terms? It means converting visual input into structured information. For example, a system may decide that an image contains a dog, locate the dog with a box, estimate the dog’s pose, or separate the dog from the background. In each case, the machine is not experiencing the scene. It is transforming pixel values into outputs that a program can use.
A useful mental model is to think of computer vision as a pipeline. First, a camera or sensor captures light. Next, the system stores that captured scene as digital values. Then algorithms or trained models analyze those values to detect patterns. Finally, the system returns a result such as a label, box, mask, count, warning, or control signal.
Beginners often assume a model “understands” an image in a broad human sense. That is a mistake. A model is usually narrow and task-specific. A model trained to classify fruit may work well on apples and bananas but fail badly on X-ray images or road scenes. This is why defining the task clearly matters. Are you asking for classification, detection, or segmentation? Are you trying to count objects, track them across frames, or estimate whether an event is dangerous? A practical vision engineer starts by defining the exact decision the system needs to make.
Seeing, for a computer, is therefore less about awareness and more about measurable output. If the system can reliably turn an image into useful, repeatable information, then in a practical sense it is seeing.
To understand computer vision, you need a simple picture of what a digital image is. A photo is made of tiny picture elements called pixels. Each pixel stores numeric values that represent light intensity and color. In a grayscale image, one number may describe brightness. In a color image, three numbers often represent red, green, and blue channels. Put millions of these pixels together, and the result looks like a continuous scene to us.
Resolution tells you how many pixels an image contains, such as 1920 by 1080. Higher resolution can preserve more detail, but it also increases storage, memory, and processing cost. That trade-off appears everywhere in computer vision. More detail can help detect small objects, but too much detail may slow a real-time system. Engineering is often about choosing enough information rather than the maximum possible information.
Video adds time. A video is a sequence of frames, where each frame is an image. If those frames are shown quickly, we perceive motion. For a vision system, video creates both opportunity and complexity. A single image can answer “what is here now?” Video can also answer “what changed?”, “where is it moving?”, and “what happened over time?” That is useful for tracking people in a store, identifying sudden braking in traffic, or spotting activity in security footage.
Light matters more than beginners expect. Cameras do not capture objects directly. They capture light reflected from surfaces or emitted by sources. Bright sun, dim rooms, glare, shadows, fog, and motion blur all change the pixel values that the model sees. A system that works well in a lab may struggle in the real world because the visual data changed. This is why data quality is not a side issue. It is part of the problem itself.
One practical rule is this: if humans would say an image is too dark, too blurry, too far away, or badly framed, a model will usually struggle too. Another rule is that labels must match the visual evidence. If your training examples are inconsistent, the model learns confusion. Visual data is only useful when capture conditions, labels, and intended use are aligned.
Computer vision is already part of daily life, often in ways people barely notice. On phones, it powers face unlock, portrait mode, photo search, document scanning, automatic rotation, barcode reading, and camera enhancements. When your phone groups similar photos, blurs the background behind a person, or identifies text in an image, a vision model is likely involved. These systems are designed for speed and convenience, often running directly on the device.
In cars, computer vision helps driver assistance systems interpret the road. A vehicle may detect lane markings, nearby pedestrians, traffic signs, brake lights, or other vehicles. Here the distinction between tasks becomes important. A classification model might decide whether an image contains a stop sign somewhere. A detection model would draw a box around the stop sign so the system knows where it is. A segmentation model could label the drivable road surface pixel by pixel, which is useful for path planning.
Stores use vision for inventory checks, shelf monitoring, self-checkout assistance, people counting, loss prevention, and queue analysis. In these cases, the practical goal is rarely “understand everything in the scene.” Instead, the goal is focused: count products, detect empty shelf space, estimate wait time, or flag suspicious motion. Strong systems succeed because they solve one clear business problem well.
These examples also show why outputs must be readable. A detection system may return a label such as “person,” a box with coordinates, and a confidence score like 0.91. That does not mean the system is 91% correct in a general sense. It means the model assigned a strong score to that prediction under its learned internal patterns. Engineers decide how to use that score. In a photo app, a low-confidence guess may be acceptable. In a car, the threshold may need to be much stricter, and uncertain predictions may trigger safer fallback behavior.
The lesson is practical: computer vision is most useful when matched carefully to context. The same core ideas appear in phones, cars, and stores, but the acceptable error, speed, and safety requirements are very different.
Computer vision matters because so much important information in the world is visual. People inspect products, read signs, watch patients, monitor crops, examine scans, and navigate streets using sight. If machines can convert images and video into reliable signals, many tasks become faster, cheaper, safer, or more scalable.
In healthcare, vision can help analyze medical images, count cells, or detect patterns that deserve a human expert’s attention. In manufacturing, cameras can inspect parts for defects at speeds that are difficult for people to maintain continuously. In agriculture, drones and field cameras can watch crop health, estimate yield, or spot disease early. In logistics, warehouses can scan packages, read labels, and monitor flow. In public infrastructure, vision systems can help track traffic, monitor road conditions, or inspect bridges and power lines.
But importance does not mean automatic success. Vision systems matter most when they are built with clear practical outcomes. Before training a model, good teams ask questions like these: What exact decision will this system support? What is the cost of a false positive? What is the cost of a false negative? How much delay is acceptable? What conditions will the camera face in the real world? What happens when the model is uncertain?
This is where engineering judgment becomes central. A model with high average accuracy may still fail on the situations that matter most, such as nighttime scenes, rare defects, or underrepresented product types. A common beginner mistake is optimizing one summary metric and ignoring the deployment environment. Another is using training data that looks clean and balanced while real-world data is messy and uneven.
Computer vision matters not because it replaces human judgment everywhere, but because it can extend human capability. It can watch more frames than a person, flag events faster, and support decisions with consistent measurement. The best applications usually combine machine speed with human oversight, especially when stakes are high.
Computers are very good at repetition, scale, and measurement. A vision system can process thousands of images, apply the same rules every time, and never get tired. It can count objects in a frame, compare similar scenes, detect small statistical differences, and work continuously in ways that would exhaust a human reviewer. This makes computers valuable for inspection, monitoring, sorting, and retrieval tasks.
Computers are also good at learning narrow patterns when enough suitable training data exists. If you provide many labeled examples of scratches on metal parts, a model can often learn to find similar scratches in new images. If you provide labeled traffic scenes, it can learn to detect cars, signs, and pedestrians. With clear labels and representative data, models can become impressively effective.
However, computers are bad at flexible common-sense reasoning unless the task is tightly framed. A person can infer that a child wearing a costume is still a child, or that a partially hidden mug is probably still a mug. Models may fail if the visual pattern differs from training examples. They can also be misled by unusual backgrounds, strange lighting, camera angle changes, or rare object appearances.
Another weakness is dependence on labels and data coverage. Training data teaches the model what to pay attention to. If examples are biased, limited, or mislabeled, the model will inherit those problems. A model that performs well on clear daytime images may fail in rain or at dusk because it never learned that part of the world.
Practically, this means you should trust computers most on well-defined visual tasks with stable conditions and measurable outputs. You should be cautious when conditions change often, edge cases matter, or context and intent are essential. Good system design includes uncertainty handling, human review when needed, and ongoing monitoring after deployment.
A complete vision system is more than a model file. It is a workflow. First, you define the problem. For example, do you want to classify whether an image contains damage, detect where products are located, or segment the road surface in front of a vehicle? Choosing the correct task type matters because it determines the data you need, the labels you create, and the outputs you expect.
Next comes data collection. You gather photos or video that reflect the real environment: different lighting conditions, angles, object sizes, backgrounds, and edge cases. Then comes labeling. For classification, labels may be image-level tags such as “cat” or “not cat.” For detection, labels usually include bounding boxes and class names. For segmentation, labels may be pixel-level masks that trace object boundaries. This annotation work is expensive but essential because the model learns from the quality of these examples.
After that, you train a model. During training, the model adjusts internal parameters to reduce errors on labeled data. Once trained, you evaluate it on separate data to see how well it generalizes. Then you deploy it into an application, where it receives new images and returns predictions. Those predictions often appear as boxes, labels, masks, and confidence scores.
The last step, often ignored by beginners, is iteration. Real-world results reveal gaps in data and labeling. Maybe small objects are missed. Maybe reflective packaging causes false detections. Maybe the confidence scores are too optimistic. Engineers then collect new examples, improve labels, adjust thresholds, retrain, and test again.
This is the big picture you should keep in mind as you continue the course. Computer vision is the engineering of turning pixels into decisions. The details will get more technical later, but the foundation stays the same: visual data in, learned pattern matching in the middle, useful action out.
1. What is computer vision mainly trying to help computers do?
2. How does a computer represent an image at a basic level?
3. Which choice best describes detection rather than classification or segmentation?
4. What does a model's confidence score mean?
5. According to the chapter, why does the whole vision pipeline matter?
Create a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log in
- Learning Evolved.
- Intelligence Amplified.


