Computer Vision — Beginner
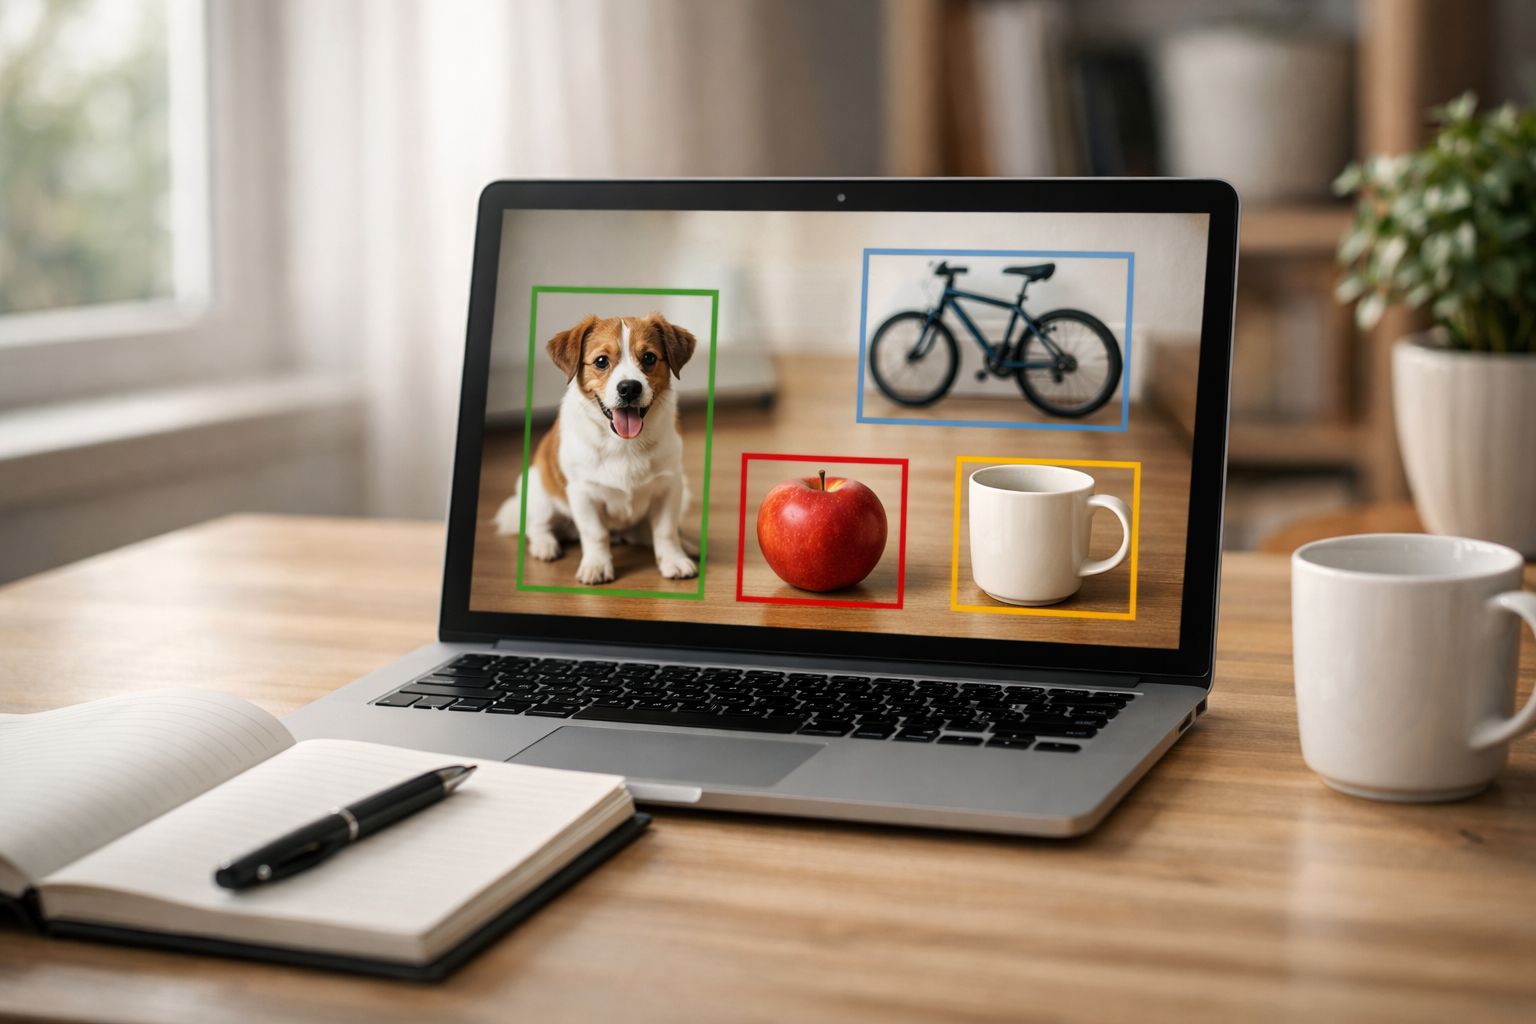
Learn how AI finds and names objects in everyday photos
This beginner course is a short, book-style journey into one of the most useful areas of computer vision: recognizing objects in photos. If you have ever wondered how a phone can identify a dog, how an app can sort pictures of food, or how online services can understand what appears in an image, this course explains the core ideas in plain language. You do not need a technical background, coding skills, or any prior knowledge of AI.
The course is designed like a six-chapter mini book. Each chapter builds naturally on the one before it, so you never have to guess what comes next. We start with the basic question of what object recognition is and why it matters. Then we move into how computers read images, how labeled examples teach an AI system, how a simple recognition model is created, how results are measured, and finally how to use these systems responsibly in the real world.
Many AI courses assume you already know programming, math, or data science. This one does not. Every concept is introduced from first principles. You will learn what a pixel is, how an image becomes data, what a label means, and why some predictions are strong while others are weak. Instead of overwhelming you with technical language, the course focuses on understanding. By the end, you will be able to explain the full object recognition workflow in simple terms.
This course is a good fit if you are curious about AI, exploring a new career path, supporting a business project, or simply trying to understand the technology behind modern photo tools. If you are ready to begin, Register free and start learning step by step.
The structure of this course matters. Chapter 1 gives you the big picture and defines object recognition in everyday terms. Chapter 2 explains how computers interpret photos through pixels, colors, and numerical patterns. Chapter 3 introduces teaching by example, including labels, categories, and dataset organization. Chapter 4 walks through making a simple recognizer with a beginner-friendly workflow. Chapter 5 shows you how to judge results and improve mistakes. Chapter 6 expands your understanding with practical use cases, privacy basics, bias awareness, and safe deployment thinking.
Because the course follows a book-like path, it is ideal for learners who want confidence, not confusion. You always know where you are in the journey, and each chapter prepares you for the next. If you want to explore more topics after this one, you can also browse all courses on the platform.
Object recognition is one of the most visible forms of AI in everyday life. It powers features in phones, shopping apps, image libraries, safety tools, and smart devices. Understanding how it works helps you become a more informed user, teammate, and decision-maker. Even if you never build advanced models yourself, this course gives you a strong foundation for talking about computer vision with confidence.
By the end of the course, you will not just know the buzzwords. You will understand the full beginner workflow: what the system sees, how it learns, how it predicts, how it fails, and how to think about using it responsibly. That makes this course an ideal first step into AI for anyone starting from zero.
Computer Vision Instructor
This course is written and kept up to date by the Edu AI Last Faculty, the course team of Edu AI Last. If you have a question about any lesson, ask the course assistant on this page at any time.
Object recognition sounds technical, but the core idea is simple: a computer looks at a photo and tries to answer the question, “What is in this image?” In this course, you will learn that this is not magic and not human-like sight. It is a practical engineering process built from digital images, patterns, labels, and predictions. The goal of this chapter is to make that process feel concrete and approachable before you touch any tools.
When people hear the term AI, they often imagine a machine that understands the world exactly as a person does. In everyday practice, AI usually means software trained to notice patterns in data and make useful guesses. In computer vision, the data is made of images. A photo that looks obvious to you—a dog on grass, a mug on a desk, a stop sign near a road—is, to a computer, just a grid of pixel values. Object recognition is the step where software turns those raw values into a predicted label such as “dog,” “mug,” or “stop sign,” often with a confidence score that says how sure it is.
This distinction matters because beginners often overestimate what an image model can do. A recognition system may identify a bicycle but fail when the bicycle is partly hidden, poorly lit, unusually colored, or photographed from an uncommon angle. Good engineering judgment starts with realistic expectations. These systems are useful because they are fast, scalable, and often accurate enough for real tasks. They are also limited because they only learn from examples and can make mistakes in situations that seem easy to people.
As you move through this course, you will build a practical mental model of the workflow. First, you gather photos that represent the objects you care about. Then you decide what labels you want, such as “apple,” “banana,” and “orange.” Next, you test a beginner-friendly recognition tool on these images and inspect its predictions and confidence scores. Finally, you look at failure cases: blurry pictures, cluttered backgrounds, shadows, reflections, and similar-looking objects. This workflow is the foundation of almost every real computer vision project, even when the tools become more advanced.
You will also start learning the language of image AI in a precise but simple way. A label is the category name you want the system to use. A prediction is the category the model chooses for a specific image. A confidence score is a number, often shown as a percentage, that estimates how strongly the model believes its prediction. These three ideas are easy to mix up at first, but keeping them separate will help you evaluate results clearly and avoid common beginner mistakes.
This chapter connects the big picture to everyday examples. You already use object recognition when your phone groups photos of pets, when an app suggests what is in a picture, when a shopping platform identifies products, or when a driver-assistance system notices road signs. By the end of this chapter, you should be able to explain object recognition in plain language, describe how a computer “reads” a digital image, and understand why careful photo choice matters. That foundation will make the hands-on parts of the course far easier and far more meaningful.
Think of this chapter as your translation guide between human intuition and machine behavior. If you can explain what the model is actually doing, you will be in a strong position to prepare better images, judge results honestly, and improve a simple recognition task step by step. That is the beginner mindset this course is designed to build.
Practice note for Understand what AI is in everyday language: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
Artificial intelligence, in everyday language, is software that learns patterns from examples and uses those patterns to make decisions or guesses. In this course, the examples are photos. When we say a computer “sees,” we do not mean it experiences sight the way a person does. A person looks at a photo and instantly uses memory, context, and common sense. A computer receives a digital image as a structured grid of pixels, where each pixel has numeric values such as red, green, and blue intensity. The model processes those values mathematically.
This difference is the first important mindset shift for beginners. If a person sees a cat partly hidden behind a chair, they still call it a cat because they understand the scene. A beginner-friendly AI model may only succeed if it has seen enough similar examples during training. If the lighting is strange, the angle is unusual, or the cat blends into the background, the model may struggle. That does not mean the system is broken. It means object recognition depends on patterns present in the data.
In practical terms, a digital image is a matrix of numbers. The model looks for visual features that often appear together: edges, textures, colors, shapes, and higher-level patterns. Modern tools automate the difficult math, but the engineering judgment still belongs to you. You decide whether your photos are clear, whether your labels are sensible, and whether the results are good enough for your task.
A useful beginner rule is this: AI is not understanding in the human sense; it is pattern recognition at scale. That is why you can test it with a no-code tool. You do not need to build the mathematics yourself to understand the workflow. You only need to know what goes in, what comes out, and why image quality and consistency matter.
In object recognition, an object is usually a thing or category you want the system to identify in a photo. That sounds easy until you start choosing labels. Is “fruit” the object, or are “apple,” “banana,” and “orange” the objects? Is “car” enough, or do you need “sedan,” “truck,” and “bus”? The answer depends on your goal. Good project design starts by defining categories that are clear, practical, and visually distinguishable.
For beginners, it is best to choose labels that are concrete and easy to tell apart. If you collect photos of mugs and bottles, the categories should have visible differences. If your categories are too broad, the results may be vague. If they are too narrow, the model may confuse similar classes. This is where engineering judgment matters. You want labels that help answer a real question without creating unnecessary complexity.
Another practical issue is image composition. A photo may contain one main object, many objects, or background clutter that distracts the model. If your task is simple object recognition, you usually want photos where the intended object is visible and reasonably prominent. That does not mean every image must be perfectly centered. In fact, some variety is healthy. But if the object is tiny, cut off, or hidden, you should expect weaker performance.
When preparing a small photo set, review each image with three questions: What is the main object? Is the label obvious? Would another person likely agree with the label? This simple check prevents many beginner mistakes. It also prepares you for later lessons, where you will compare labels with the model’s predictions and confidence scores. Clear labels produce clearer evaluation and faster learning.
Many beginners use several computer vision terms as if they mean the same thing, but they solve different problems. Object recognition usually means assigning a label to an image or to the main object in that image. If you show a model a photo and it outputs “dog,” that is recognition or image classification. Object detection goes further by finding where the object is, often drawing a box around it and labeling each instance. Image description or captioning goes further still by generating a sentence such as “A brown dog running through grass.”
Why does this distinction matter? Because your expectations should match the tool. If you upload a picture with three apples and two bananas to a simple recognition tool, it may only say “fruit” or “banana” depending on what dominates the image. That is not the same as counting each item. Detection would be the better fit for that task. Likewise, if you want a full sentence about the scene, a classifier is not enough.
This is also the right place to understand labels, predictions, and confidence scores. A label is the correct category name you assign to training or test images. A prediction is the model’s output for one image. A confidence score expresses how strongly the model leans toward that prediction. A high confidence score can still be wrong, especially if the image is unusual or your categories overlap. A low confidence score may signal ambiguity, poor image quality, or that the object is not well represented in the model’s prior examples.
In practice, beginners should avoid reading confidence as certainty. Treat it as a useful clue, not a guarantee. Good evaluation means comparing the model’s prediction to the intended label and then inspecting the photo itself. Ask what visual factors may have helped or confused the system.
Object recognition already appears in many products people use without thinking about the underlying technology. Your phone may organize photos by categories such as dog, beach, food, or car. A shopping app may identify products from a camera image. A social media platform may suggest alt text or help search your photo library. Driver-assistance systems may classify signs, lane markers, pedestrians, or vehicles. Even a recycling app may estimate whether an item is a bottle, can, or paper container.
These examples matter because they show the practical goal of object recognition: turning visual input into useful actions. In one product, the action is search. In another, it is safety. In another, it is convenience. The technical core is similar, but the standard for quality changes. A casual photo search tool can tolerate occasional mistakes. A road-related system needs much stricter testing. This is a key engineering lesson: success depends on context, not just average accuracy.
Looking at daily-life systems also helps you notice common failure modes. Phones may misgroup images taken in poor light. Shopping tools may confuse visually similar packaging. Camera apps may struggle with reflective surfaces, tiny objects, or objects partly hidden behind others. These are not random problems. They usually come from gaps between the images the model learned from and the images users provide in the real world.
As a beginner, start observing these systems around you. When they succeed, ask what made the image easy. When they fail, ask what changed: background clutter, unusual angle, shadows, motion blur, low resolution, or overlapping objects. This habit builds intuition that will help you prepare better photo sets and judge model outputs more realistically.
You do not need programming to begin learning object recognition well. In fact, many beginners learn faster at first by using no-code or low-code tools because they can focus on the ideas instead of software setup. A beginner-friendly vision tool lets you upload images, assign labels, run a model, and inspect predictions. That gives you direct contact with the workflow: collect photos, organize them, test the model, review results, and adjust your data.
This approach teaches the right habits early. You learn that better data often matters more than more complexity. You learn to look at edge cases rather than trusting a single impressive example. You learn that image selection is a design decision. For example, if every training photo of a mug is on the same desk from the same angle, the model may accidentally rely on the desk background instead of the mug itself. A little variety in lighting, distance, angle, and background can produce a more robust result.
A practical beginner exercise is to prepare a small photo set with two or three simple classes, such as cup, bottle, and book. Keep the labels consistent. Remove images that are too blurry or mislabeled. Then test a beginner-friendly tool and note each prediction and confidence score. Do not just count correct answers. Look for patterns in the mistakes. Are side views harder than front views? Do dark objects fail more often? Does cluttered background increase confusion?
This is real computer vision practice. Coding becomes valuable later, but the core skill starts with observation, careful labeling, and honest evaluation. If you can explain what your model is doing and why it fails, you are already learning the discipline correctly.
This course is designed to move from understanding to doing. First, you will build a simple mental model of what AI object recognition does and how computers read images as data. Then you will learn the practical vocabulary of labels, predictions, and confidence scores. After that, you will prepare a small photo set for a basic task and test it with an accessible tool. Along the way, you will examine common mistakes and learn how to improve your setup without needing advanced math or programming.
Your final beginner project will be small by design, because small projects teach the essentials clearly. You might create a mini recognizer for everyday objects such as cups, books, and phones, or for simple food items such as apples, bananas, and oranges. The project workflow will be straightforward: define labels, gather images, check image quality, run the tool, review predictions, and inspect failure cases. The value is not in building a perfect system. The value is in understanding the full loop from data to result.
As you continue, keep your standards practical. A beginner project should answer a narrow question well enough to demonstrate understanding. If the model confuses a bottle with a cup in a few difficult images, that is not failure. It is information. You will learn to diagnose whether the issue comes from poor labels, unbalanced photos, weak image variety, or limitations of the recognition tool itself.
By the end of the course, you should be able to explain object recognition in simple words, prepare a small test set, use a no-code tool to evaluate images, and spot common system mistakes with confidence. That combination of conceptual clarity and hands-on judgment is the real goal of this first chapter and the foundation for everything that follows.
1. What is object recognition mainly trying to do?
2. How does a computer typically 'see' a photo in object recognition?
3. Which choice correctly matches the meaning of a confidence score?
4. Why might an object recognition system fail to identify a bicycle correctly?
5. Which example from everyday life best shows object recognition in use?
Create a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log in
- Learning Evolved.
- Intelligence Amplified.


