Computer Vision — Beginner
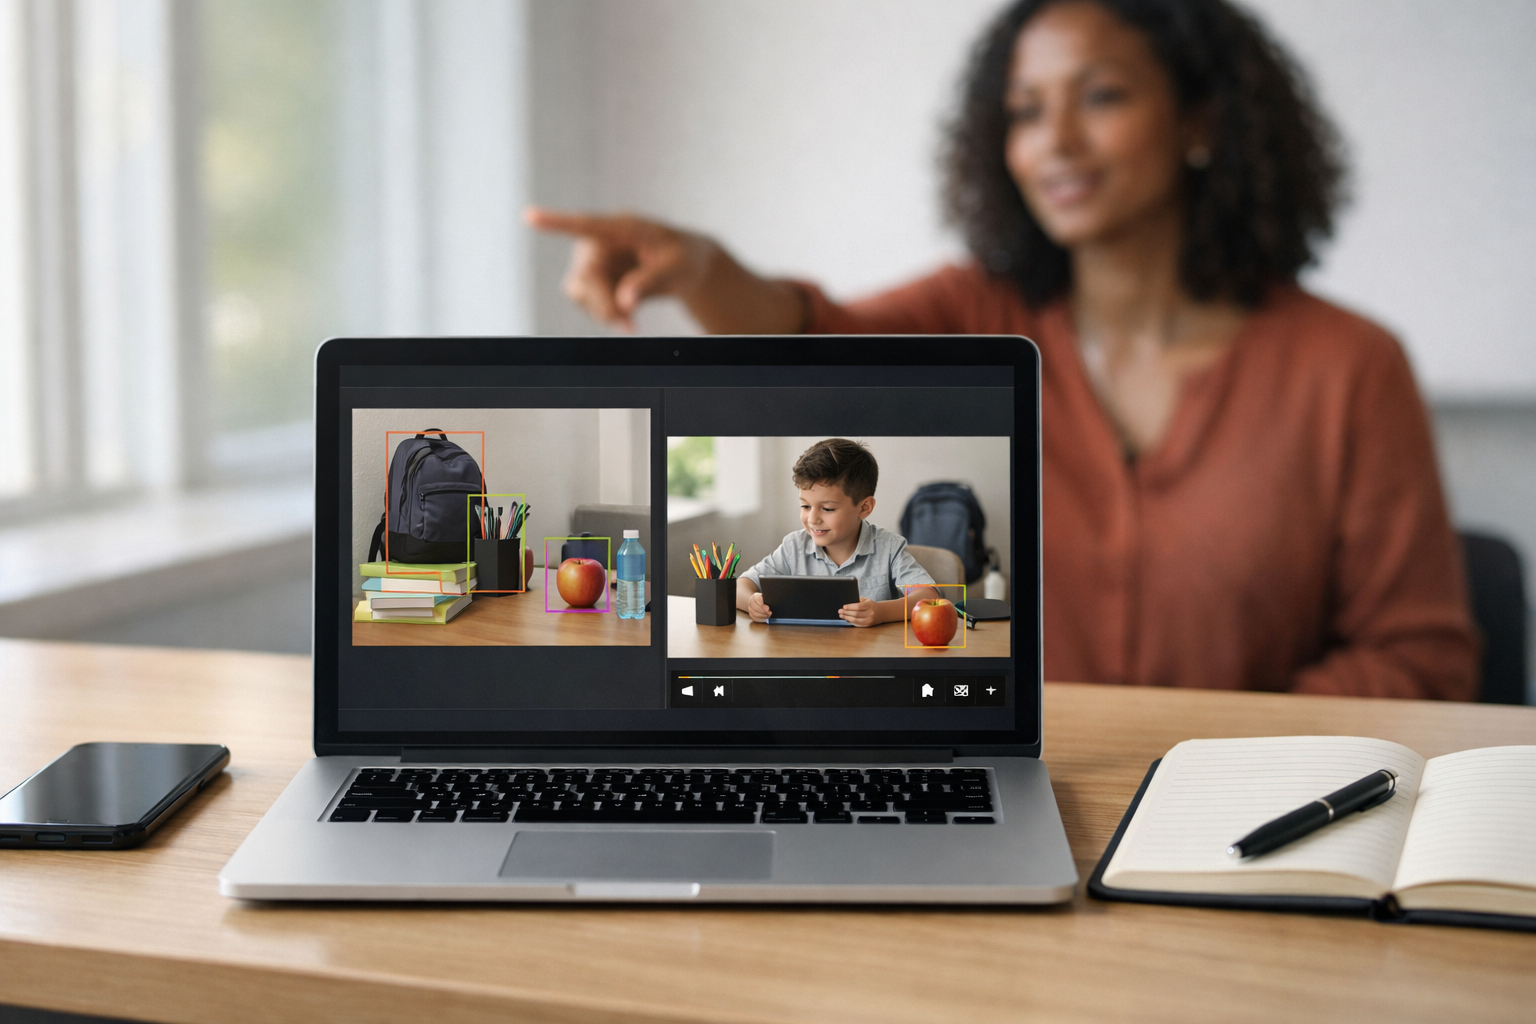
Learn to spot objects in images and video from zero
This beginner course is a short, book-style introduction to one of the most useful areas of computer vision: object detection. If you have ever wondered how a phone camera can recognize faces, how a self-checkout system can identify products, or how software can spot people and cars in video, this course will help you understand the ideas in plain language. You do not need any previous experience in AI, programming, machine learning, or data science.
The course is designed like a short technical book with six connected chapters. Each chapter builds on the last one, so you will not be thrown into advanced concepts too early. Instead, you will move step by step from the basic idea of how computers look at images to the practical reality of detecting objects in both photos and videos.
Many AI courses assume you already understand coding, math, or technical vocabulary. This course does the opposite. It starts from first principles and explains every key idea using simple examples from daily life. You will learn what an object detector does, what a box and label mean on screen, why confidence scores matter, and how image quality affects results.
You will also learn the difference between related concepts that beginners often mix up, such as image classification, object detection, and object tracking. By the end, these ideas will feel practical rather than abstract.
In the first part of the course, you will learn how a computer turns an image into data and how AI systems use patterns to identify objects. Then you will look at the building blocks of object detection, including labels, bounding boxes, and confidence scores.
Next, the course shifts to image preparation. This is important because beginners often think AI success depends only on the model, when in fact photo quality, lighting, object angle, and background clutter can make a major difference. After that, you will move into video and see how object detection works frame by frame, as well as why tracking objects over time is more difficult than analyzing a single image.
The final chapters focus on errors, trust, and project planning. You will learn why object detectors sometimes miss items, why they sometimes report objects that are not really there, and how to think critically about results. Finally, you will bring everything together by planning a small, realistic beginner project based on a simple use case.
Object detection is a foundation skill in modern computer vision. It supports applications in retail, safety, transportation, healthcare, smart devices, manufacturing, and public services. Even if you do not plan to become an engineer, understanding how these systems work will help you evaluate AI tools more confidently and communicate better with technical teams.
This course is especially useful for curious learners, professionals exploring AI for work, and anyone who wants a solid, non-intimidating introduction to visual AI. If you want to continue learning after this course, you can browse all courses to find your next step.
By the end of the course, you will be able to describe object detection clearly, interpret basic detection results, recognize common quality issues in images and video, and plan a simple project with realistic goals. You will not just memorize terms. You will build a practical mental model of how AI spots objects and what affects its performance.
If you are ready to start learning computer vision in a clear and approachable way, this course is a strong first step. Join today and Register free to begin building confidence with AI for images and video.
Computer Vision Instructor
This course is written and kept up to date by the Edu AI Last Faculty, the course team of Edu AI Last. If you have a question about any lesson, ask the course assistant on this page at any time.
Object detection is one of the most useful and visible parts of modern computer vision. When people say that AI can “see,” they usually do not mean that a computer understands the world the way a person does. They mean that software can examine image data, spot useful patterns, and make predictions such as “there is a person here,” “that looks like a car,” or “a dog appears in this part of the frame.” In beginner-friendly terms, object detection is the task of finding what is present in an image or video and also where it is located.
This chapter builds the foundation for the rest of the course. You will learn what AI means in everyday language, how computers turn photos and video frames into numbers, and what object detection adds beyond simple image recognition. You will also start reading the three visual outputs that appear in most demos: boxes, labels, and confidence scores. These are not just decorations on screen. They are the model’s best attempt to describe what it thinks it found, where it found it, and how certain it feels about that guess.
A practical mindset matters from the beginning. In real projects, object detection is not magic. It depends on image quality, lighting, camera angle, motion blur, object size, and the data used to train the model. A good beginner learns early that AI systems can miss obvious objects, confuse similar items, or raise false alarms when background patterns look familiar. Those errors are normal, and understanding them is part of becoming effective with the technology.
Another important idea is that video is not fundamentally different from images. A video is a sequence of frames shown quickly one after another. If a model can detect objects in one photo, it can often be applied frame by frame to a video. Later in the course, this will help you test beginner-friendly tools on both still images and moving scenes without advanced coding.
By the end of this chapter, you should be able to explain object detection in simple language, distinguish it from classification, interpret basic on-screen outputs, and recognize common real-world uses in phones, stores, and roads. You should also have a clear picture of the workflow ahead: prepare examples, run a detector, inspect results, and judge whether the system is making useful decisions or careless mistakes.
Think of this chapter as your map. It gives you the vocabulary, mental models, and practical expectations needed for the hands-on work to come. Once these ideas are clear, beginner tools become much easier to use, because you will understand what the software is trying to do and how to judge whether it is doing it well.
Practice note for Understand what AI means in everyday language: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
Practice note for See how computers look at images and video frames: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
Practice note for Learn what object detection adds beyond simple image recognition: document your objective, define a measurable success check, and run a small experiment before scaling. Capture what changed, why it changed, and what you would test next. This discipline improves reliability and makes your learning transferable to future projects.
In everyday language, AI is software that can learn patterns from examples and then apply those patterns to new situations. In this course, the examples are visual: photos and video frames. Rather than being explicitly programmed with one rule for every possible object, a computer vision model is trained on many labeled examples so it can recognize useful visual structures such as faces, vehicles, animals, packages, or traffic signs.
Why do images matter so much? Because cameras are everywhere. Phones, doorbells, store security systems, factory inspection lines, and cars all collect visual information. That means image-based AI can help automate tasks people already do with their eyes: counting products, checking whether a person entered a room, spotting a bicycle near a road, or finding missing items in a shelf photo. The camera becomes a sensor, and AI becomes the tool that turns raw pixels into decisions.
It is important to keep your expectations realistic. AI vision is powerful, but it is not human understanding. A person can infer context from very little information. A model mainly compares patterns it sees with patterns it learned before. If the data is clear and familiar, performance can be impressive. If the scene is dark, blurry, unusual, or crowded, the system can fail.
From an engineering point of view, the value of object detection comes from turning visual scenes into structured output. Instead of saying only “this looks like a street,” the system can say “there are two cars, one pedestrian, and a bicycle in these locations.” That extra structure is what makes detection useful for alerts, counting, safety systems, and analysis dashboards.
As a beginner, your goal is not to memorize technical jargon. Your goal is to describe what the system does in plain speech: it looks at visual data, searches for learned patterns, and reports likely objects. That simple explanation will carry you through the rest of the course and help you judge tools based on practical results instead of hype.
A computer does not receive a photo as “a dog in a park.” It receives a grid of numeric values. Each image is made of pixels, and each pixel stores color information. In a common RGB image, every pixel has red, green, and blue values. A large photo may contain millions of these values. To a computer, the image begins as a table of numbers, not as meaningful objects.
This is a crucial beginner concept: vision models do not directly see cats, cups, or people. They process numeric patterns. During training, the model learns that certain combinations of edges, textures, shapes, and color arrangements often correspond to specific objects. During prediction, it compares the current image data with those learned patterns and produces guesses.
Video works in a similar way. A video is a sequence of frames, and each frame is simply another image. When an object detector runs on video, it usually analyzes frame after frame. That means practical issues such as lighting changes, motion blur, compression artifacts, and camera shake can affect detection quality. A detector that performs well on a clean photo may behave worse on fast-moving video.
In real workflows, photos are often resized before analysis because large images require more computing power. This creates a trade-off. Smaller images run faster, but tiny objects may become harder to detect. That is an early example of engineering judgment: speed, accuracy, and hardware limits must be balanced. Beginners often assume bigger images are always better, but the best choice depends on the use case and the tool being used.
When preparing examples for object detection tasks, choose clear images first. Use good lighting, avoid extreme blur, and include objects that are visible enough to be recognized. For video, start with short clips and simple scenes. Clean test inputs help you understand the tool’s behavior before you challenge it with crowded or difficult footage.
Once an image becomes numeric data, the next question is how a model finds meaning in it. The answer begins with patterns. At the smallest level, models can respond to simple visual clues such as edges, corners, brightness changes, and repeated textures. As information moves through the model, these small clues can combine into larger structures: wheels, eyes, windows, handles, or outlines of familiar object shapes.
This layered idea is useful for beginners because it explains why object detection can still work under some variation. A car may be red or blue, near or far, partly shadowed or slightly rotated, but certain patterns remain informative. At the same time, this also explains why models make mistakes. If two objects share many visual clues, or if part of an object is hidden, the system may confuse them.
On screen, object detection usually appears as a bounding box, a label, and a confidence score. The box marks the estimated location of the object. The label names the predicted class, such as person, bicycle, dog, or bottle. The confidence score expresses how strongly the model believes that prediction fits the observed pattern. A score of 0.92 generally suggests more confidence than 0.51, but it does not guarantee correctness.
Practical interpretation matters. Beginners often trust high scores too much and ignore low-score detections too quickly. In reality, a high-confidence prediction can still be wrong, especially in unusual scenes. A lower-confidence prediction may still be useful if the object is small or partly blocked. Good judgment means checking the visual evidence, not just reading the number.
Common mistakes include missed objects, duplicate boxes around one object, and false alarms caused by background patterns. These are not random defects; they reflect the model’s attempt to match visual clues under uncertainty. Learning to inspect those outputs calmly is a core skill. It helps you decide whether a problem comes from the image quality, the detection threshold, the model’s training data, or the limits of the tool itself.
One of the most important beginner distinctions in computer vision is the difference between classification, detection, and tracking. These terms are related, but they solve different problems. Image classification asks a broad question: what is in this image? A classifier might look at a photo and answer “cat” or “car.” It gives a category for the whole image or for a chosen crop, but it usually does not tell you where the object is located.
Object detection goes further. It asks: what objects are present, and where are they? If a photo contains three people and one dog, a detector can place separate boxes around each visible object and assign labels and confidence scores to each one. This makes detection much more useful for counting, locating, and reacting to individual objects in a scene.
Tracking usually appears in video applications. After detection identifies objects in each frame, a tracking system attempts to keep the identity of each object consistent over time. For example, one person walking across several frames may keep the same ID number so the system knows it is the same person, not a new one in every frame.
Understanding these differences prevents a common beginner mistake: choosing the wrong tool for the task. If you only need to know whether an image contains a cat at all, classification may be enough. If you need to know where the cat is, detection is necessary. If you need to follow the same cat across video frames, tracking becomes important.
From an engineering perspective, each step adds complexity. Classification is simpler. Detection requires localization. Tracking adds time-based consistency. In this course, object detection is the main focus, but seeing the full picture helps you understand where detection fits in larger systems and why video tools often combine multiple techniques behind the scenes.
Object detection is easiest to understand when you connect it to situations you already know. On phones, object detection helps camera apps focus on faces, separate foreground subjects from backgrounds, and organize photo libraries by detected items such as pets, food, or vehicles. In accessibility tools, it can describe parts of a scene to assist users. In home security, it can distinguish a person from a passing car or an animal in the yard.
In stores and warehouses, detection can support inventory checks, shelf monitoring, queue analysis, and package counting. A system may alert staff when a shelf appears empty, when a product is misplaced, or when a loading area contains a blocked path. The practical value is not just recognizing “store stuff.” It is locating specific objects in specific places so action can be taken.
On roads, detection is central to traffic cameras, driver assistance systems, and smart transportation tools. Cars, buses, bicycles, pedestrians, and signs may all need to be located quickly and repeatedly. In these settings, errors matter. A missed pedestrian is more serious than a mislabeled trash can. This is why engineering judgment includes understanding the cost of different mistakes, not just the average accuracy number.
These examples also show why testing with realistic inputs matters. A road detector trained on daylight scenes may struggle at night. A store detector may perform poorly when shelves are partially blocked. A phone app may do well on centered faces but fail on unusual angles. The beginner lesson is simple: always match your test examples to the environment where the tool will actually be used.
As you explore beginner-friendly detection tools, ask practical questions. What objects can this model detect? How does it behave with small objects? Does it react badly to reflections, shadows, or crowding? Can it process both images and video? Useful systems are not judged only by flashy demos. They are judged by how reliably they handle the conditions that matter in the real world.
This course is designed to move from understanding to practice. First, you will build a solid mental model of what object detection is and is not. Then you will work with simple images and videos, learn how to read outputs, and experiment with beginner-friendly tools that do not require advanced coding. The aim is to make you comfortable testing object detection systems and discussing their results clearly.
A practical workflow will guide you throughout the course. Start by choosing a small set of example images or short video clips. Pick scenes that are easy to understand, such as one or two visible objects in good lighting. Run a detection tool. Inspect the boxes, labels, and confidence scores. Ask whether the results match what a reasonable person would expect to see. If they do not, try to identify why: poor image quality, object size, clutter, or model limitations.
You will also learn to recognize common errors. A missed object means the system failed to detect something that is present. A false alarm means it detected something that is not actually there. Mislabeling means it found an object but named it incorrectly. Duplicate detections mean it drew multiple boxes for one object. These are standard failure modes, and becoming familiar with them will make your testing much more effective.
Another beginner goal is tool selection. Many no-code or low-code tools can run object detection on uploaded images or sample videos. You do not need to build a model from scratch to begin learning. What matters first is being able to observe results, compare performance across examples, and form good judgment about when the tool is useful and when it is not.
By the end of this course, you should be able to explain object detection simply, compare it with classification, prepare basic visual examples, test models with accessible tools, and discuss errors with confidence. That is a strong foundation. It means you are not just watching AI demos. You are learning to evaluate them like a careful practitioner.
1. What best describes object detection in simple language?
2. What does object detection add beyond simple image recognition or classification?
3. Why can the same detection idea often work on both photos and videos?
4. How should a beginner think about boxes, labels, and confidence scores shown by a model?
5. Which statement reflects a practical expectation about real-world object detection?
Create a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log inCreate a free account to unlock every chapter, quiz and progress tracking — 7 days of full access, no card needed.
Start free Log in
- Learning Evolved.
- Intelligence Amplified.


